Everything the model sees is recorded in an append-only session log: system prompts, reasoning, tool calls and results, subagent scheduling, and every context injection. In the Trajectory view, you can inspect these records by source. Resume, fork, search, and replay all operate on the same event stream."
That's a killer feature, IMHO, and one that US models won't allow you to do, as their traces are encrypted, obfuscated, etc. and have to be extracted via various workarounds (that violate the terms of service).
If you want to be able to improve your tools that work with models, you have to be able to assess what the models think is happening, how they think about and interact with the data you give them. And, the US models won't let you see that.
Agreed that it is a killer feature. US models obfuscate the COT (to A. make it look better and B. combat distillation) but > and the raw trace is fairly hard to reason about > but I still think this kind of feature is a big step in the right direction.
Because they are an integral part of the solution generation.
By distilling, you are training a model via Reinforcement Learning (RL) to mimic the answer of a bigger model. To do that, you need all the steps that contributed to generating an answer.
To give you a better idea, imagine teaching a student how to solve math problem:
1. You give it the problem and the answer only (no thinking trace)
2. You give it the problem, the intermediary steps and the answer (full transcript)
I think you can agree that the second method is more likely to give a well-informed student.
I agree it’s a great step. But the deepseek models also don’t perform to the same level of fable/sol. If we optimize/finetune to deepseek traces, wouldn’t it be suboptimal? What would the benefit be?
You let the smarter model explore the traces and figure out where the current harness' bottlenecks are for the current LLM. Then you can adjust prompts or tools to fix those.
That is precisely how the dreamcoder [0] ai agent I built also works.
It has an event sourced architecture in SQLite and it resolves queries using recursive CTEs (and sneaky projections to speed things up) to deliver exactly that. Identical, stable message chains to AI and complete introspection.
Bonus points include a constraint-satisfaction solver for the tiling window manager so windows never shrink too small to read. And many other keyboard-friendly features.
I'm curious, how does the context management work with event sourcing? What kind of events are you storing and how do you decide when to hydrate a new projection?
Pi can only log what the model shows it. Many models keep their thinking traces hidden and only provide a hash or something to recover it on subsequent resumes. DeepSeek shows CoT traces, and is maybe the best model that does so, I think? Kimi stopped providing CoT traces a little while ago in their subscription service via Kimi Code, I believe. I haven't checked GLM or Qwen 3.8 Max, though I guess if you're hosting the open models yourself or using an alternative inference provider there's probably got to be some way to get at that data.
Anyway, this particular harness isn't doing anything unique, but the combination of an official agent intentionally keeping the data and making it accessible to the user and a model API that provides all the information is unusual and worth calling out. It used to be common, most APIs and models and agents showed the reasoning, or could be configured to do so. Most no longer offer it.
Asking them what they think is happening is actually not reliable, though? They don't always know how they came to a conclusion after the fact. It is probable that it's roughly similar to the path they took to get there, since it's the same weights, but it's not certain. And, if you make it standard practice to always collect that data (e.g. if you have an automated tool to ask the model to explain itself after every action to log it), it seems like you might find yourself being blocked for violating terms of service. It looks like "distilling".
In short, there are workarounds, but they're not guaranteed to work forever and they're likely to bump into terms of service.


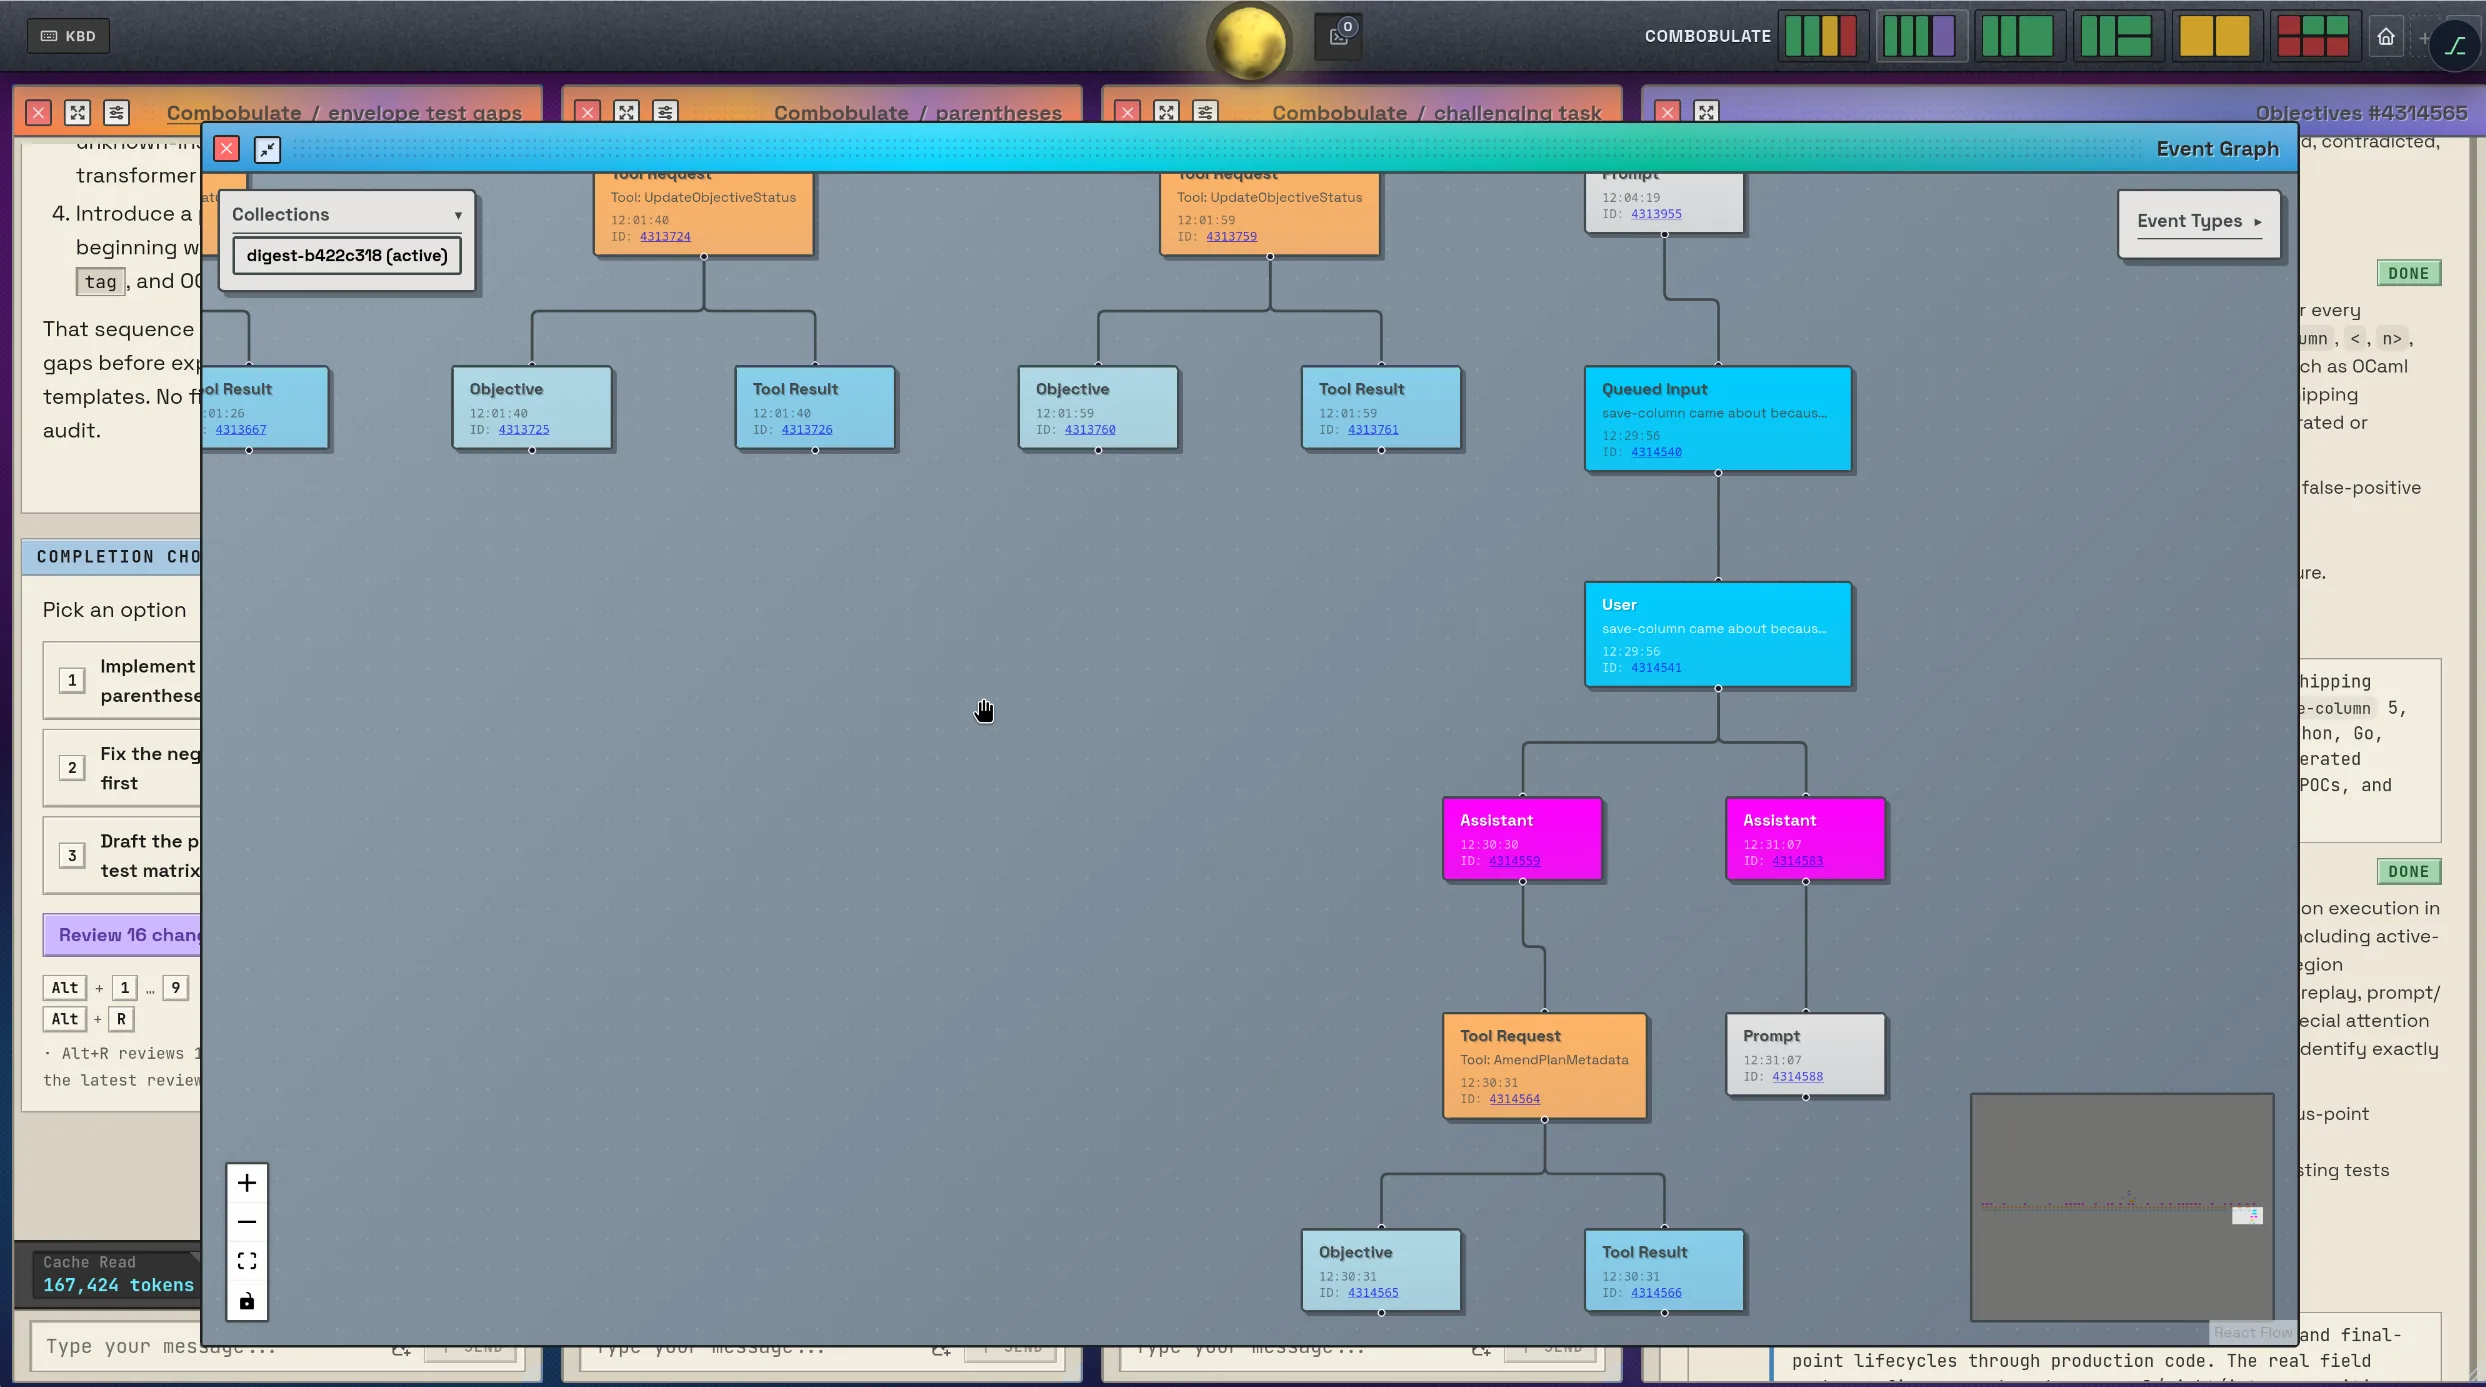
Everything the model sees is recorded in an append-only session log: system prompts, reasoning, tool calls and results, subagent scheduling, and every context injection. In the Trajectory view, you can inspect these records by source. Resume, fork, search, and replay all operate on the same event stream."
That's a killer feature, IMHO, and one that US models won't allow you to do, as their traces are encrypted, obfuscated, etc. and have to be extracted via various workarounds (that violate the terms of service).
If you want to be able to improve your tools that work with models, you have to be able to assess what the models think is happening, how they think about and interact with the data you give them. And, the US models won't let you see that.